
The DataJoint Library is a Python framework for scientific data pipelines built on the Relational Workflow Model, a paradigm in which your database schema is an executable specification of your workflow.
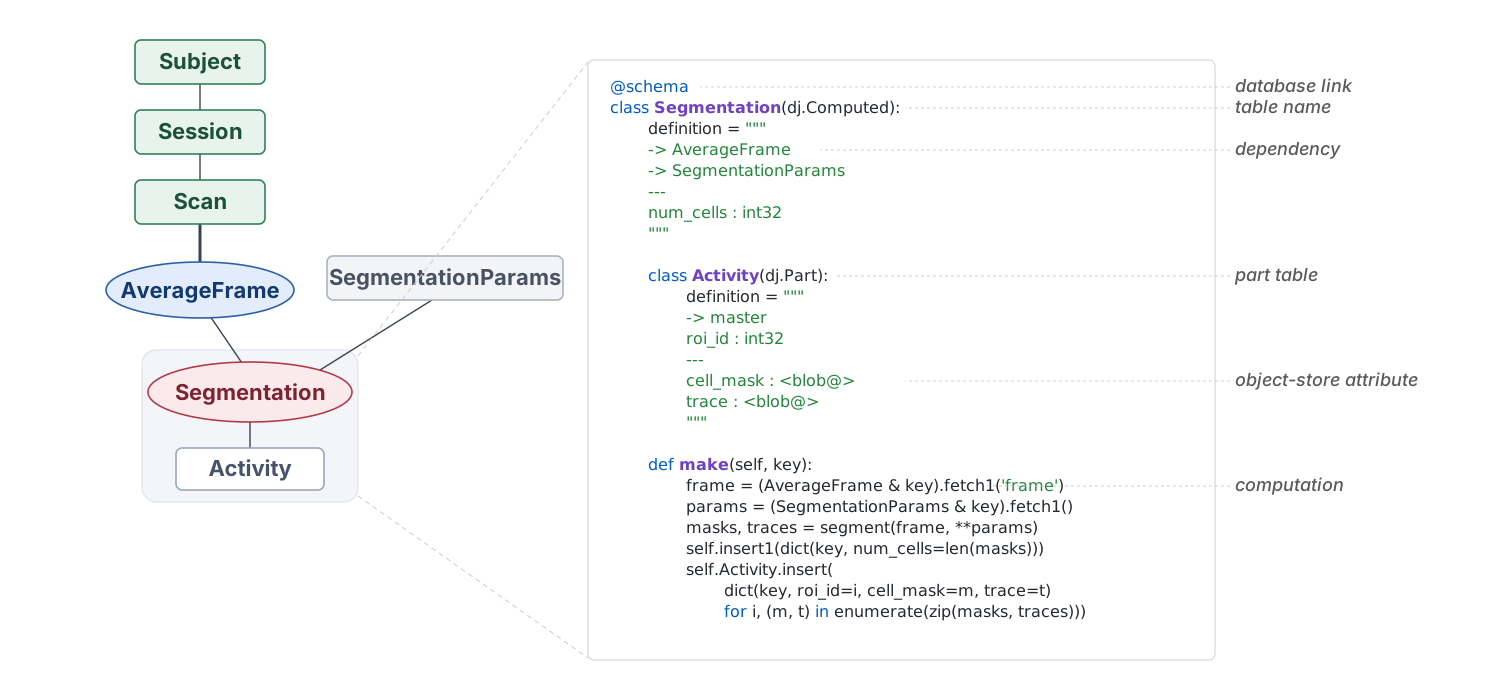
- Tables represent workflow steps: each table is a step in your pipeline.
- Foreign keys encode dependencies: parent tables are populated before their children.
- Computations are declarative: you define what to compute, and DataJoint handles when.
- Results are immutable: every result traces back to its declared inputs.
This organization hosts the DataJoint Library (datajoint-python), its documentation, codec plugins, and example pipelines.
Cite DataJoint: Yatsenko et al., 2026, DataJoint 2.0: A Computational Substrate for Agentic Scientific Workflows. RRID: SCR_014543
pip install datajointor with Conda:
conda install -c conda-forge datajoint- Documentation: tutorials, how-to guides, explanations and API reference
- Installation
- Tutorials
- Migration Guide: upgrading pipelines from DataJoint before 2.0
- DataJoint Elements: example pipelines for neuroscience experiments
- GitHub Discussions: questions and community support

